Stop Debugging
Kubernetes Manually
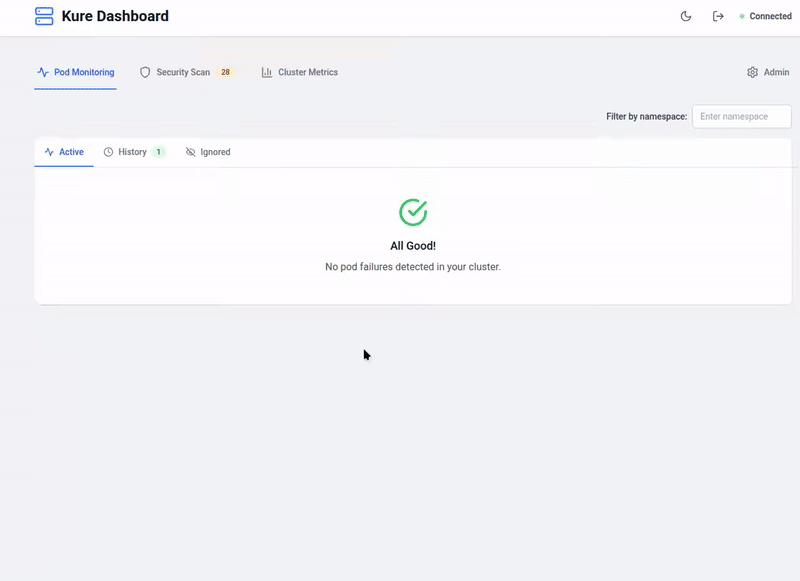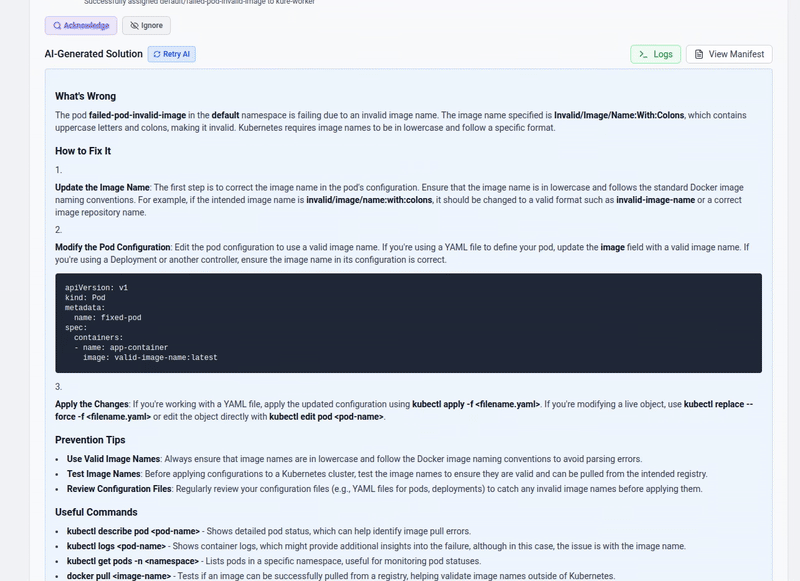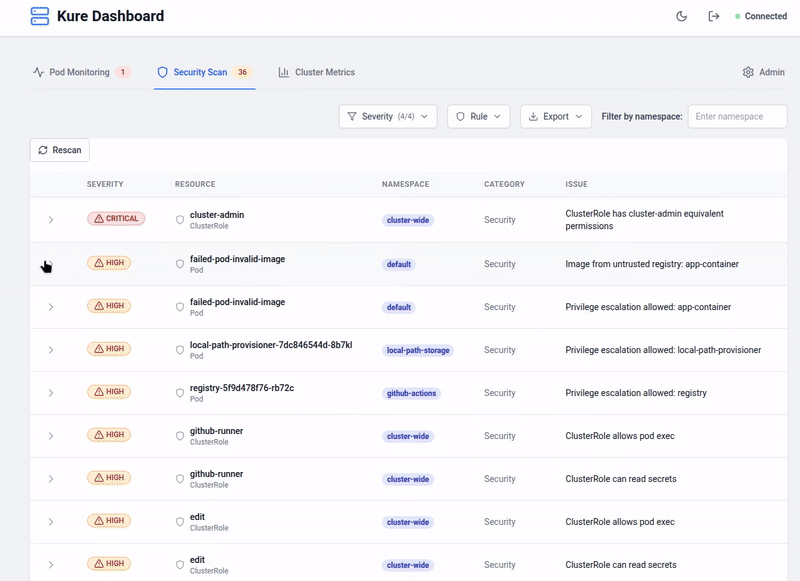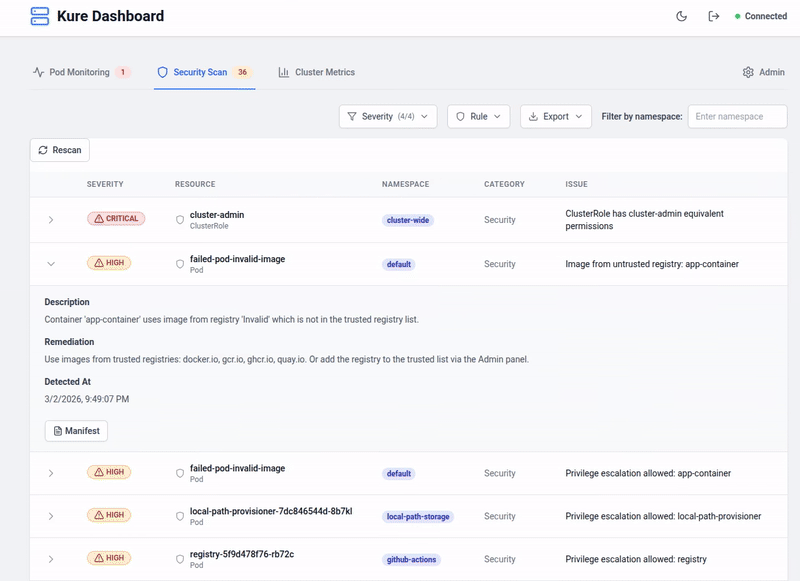
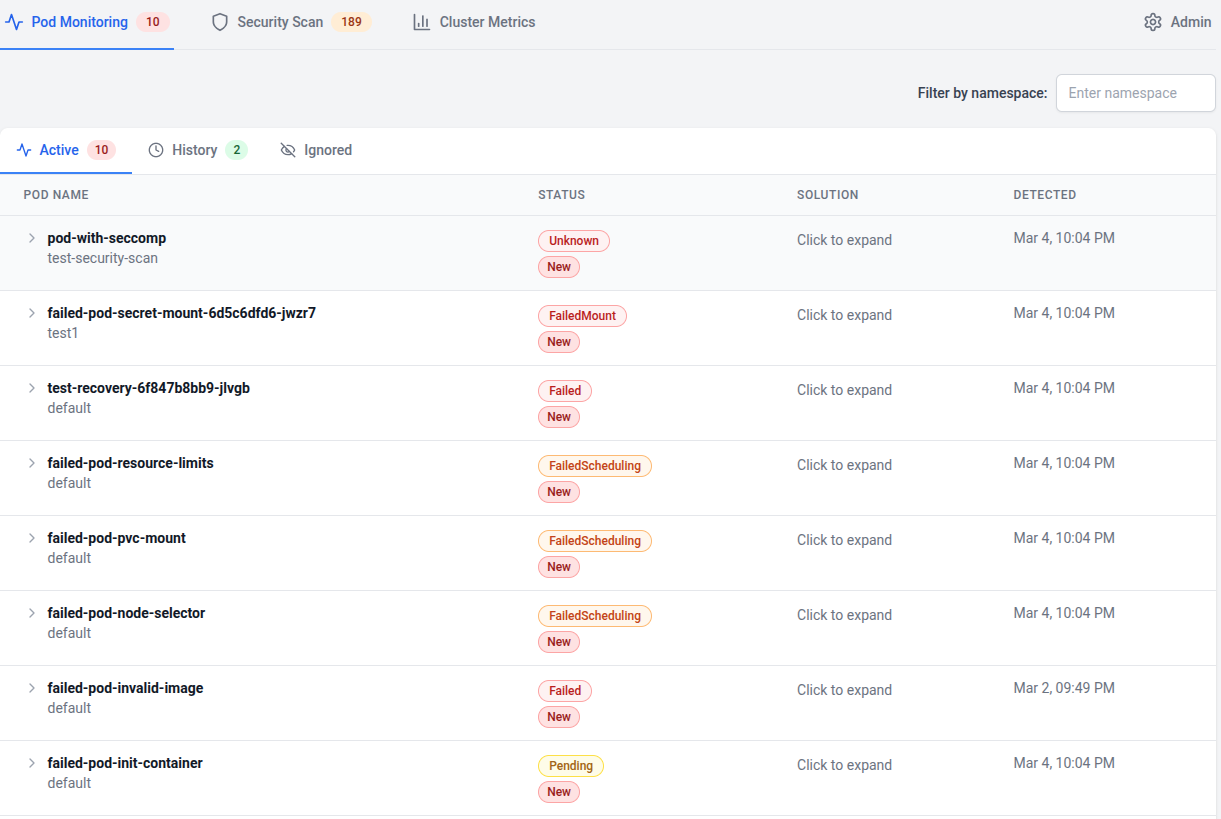
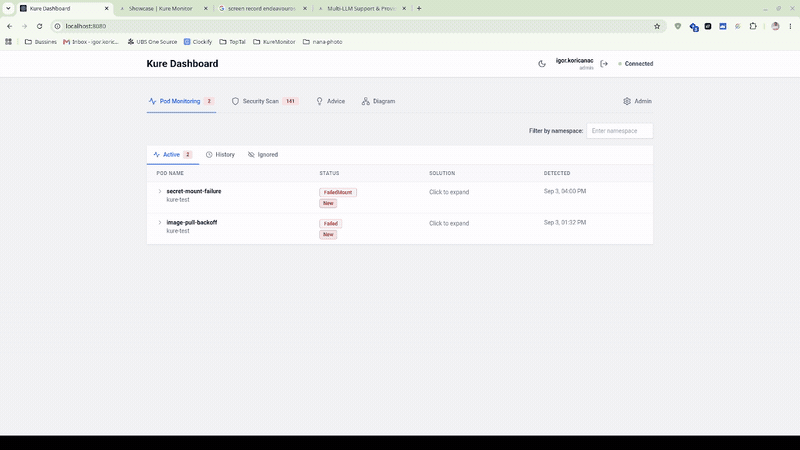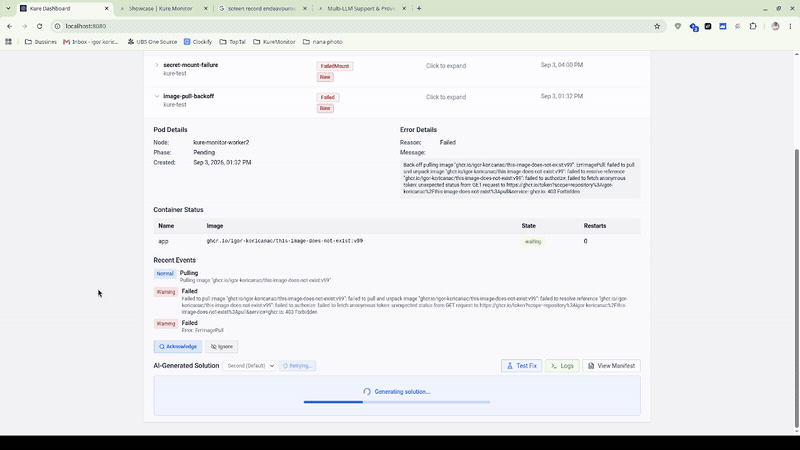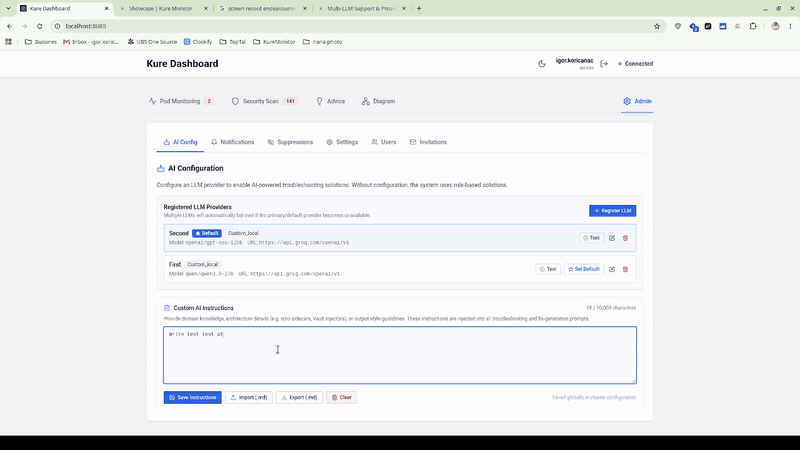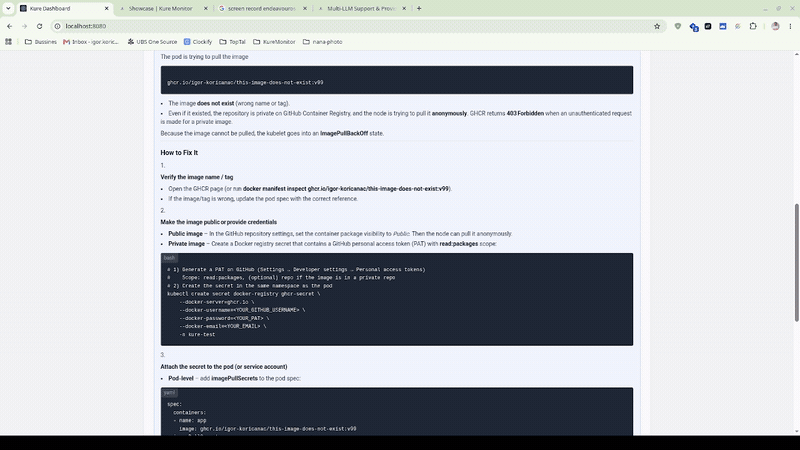
Kure detects pod crashes, image-pull errors, and scheduling issues in seconds, and uses AI to tell you exactly how to fix them. Open source and air-gapped ready.

Kure detects pod crashes, image-pull errors, and scheduling issues in seconds, and uses AI to tell you exactly how to fix them. Open source and air-gapped ready.

Kure replaces fragmented monitoring tools with a unified, AI-native platform.

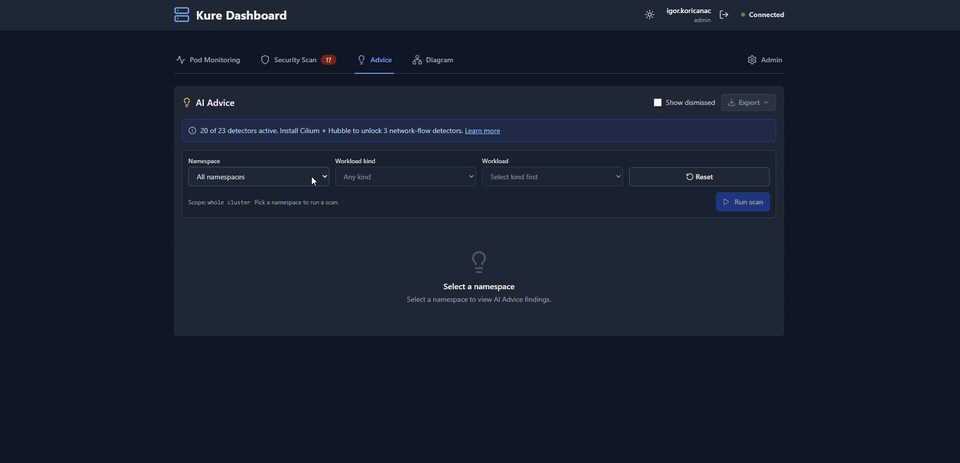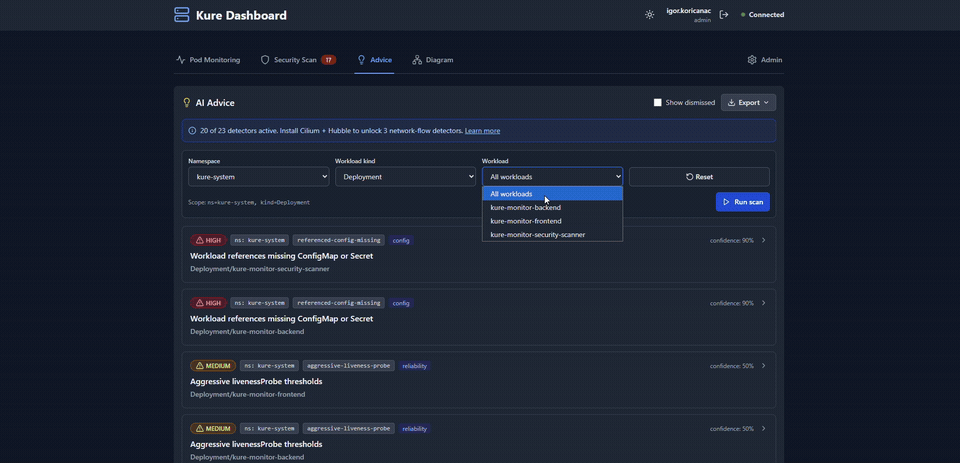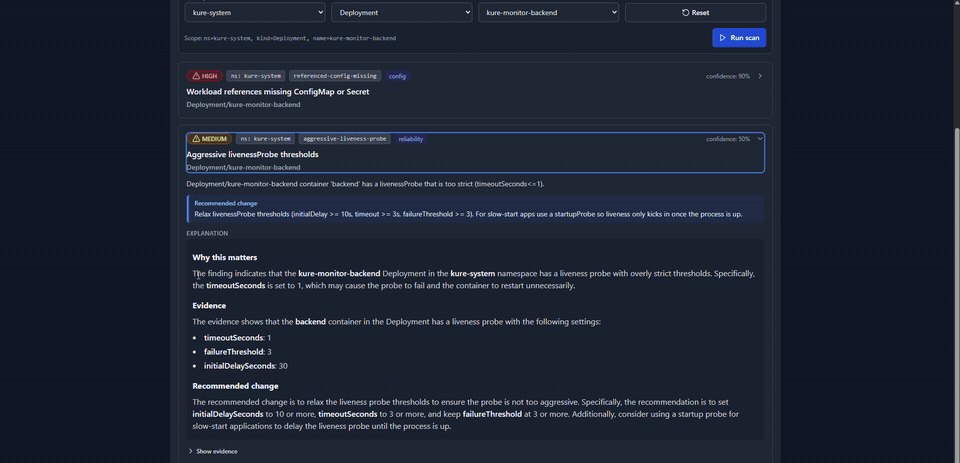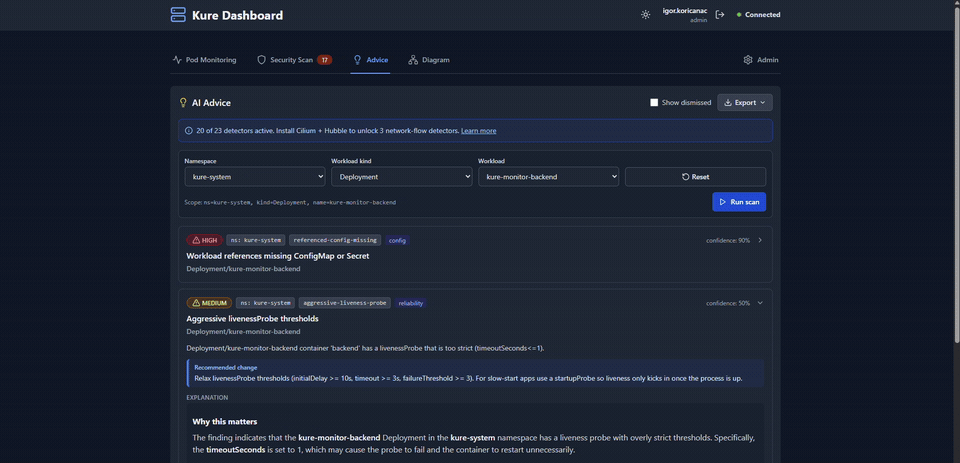
Get instant, context-aware explanations and copy-paste fixes for failing pods using local or cloud LLMs.

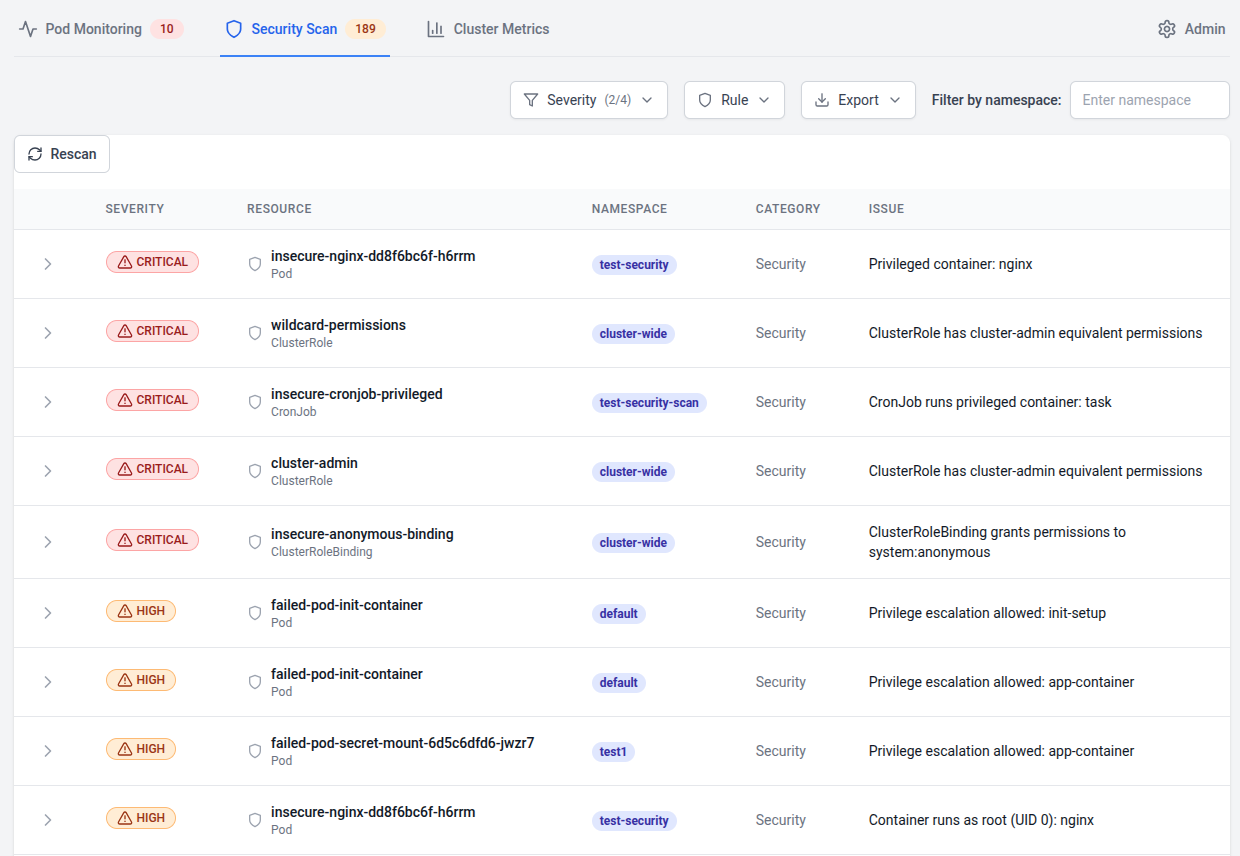
Continuously audit your cluster for 50+ misconfigurations, privileged containers, and RBAC issues.

Track Failing Pods with instant AI remediation, inspect cluster-wide Live Pods, and stream real-time container logs with play/pause controls.

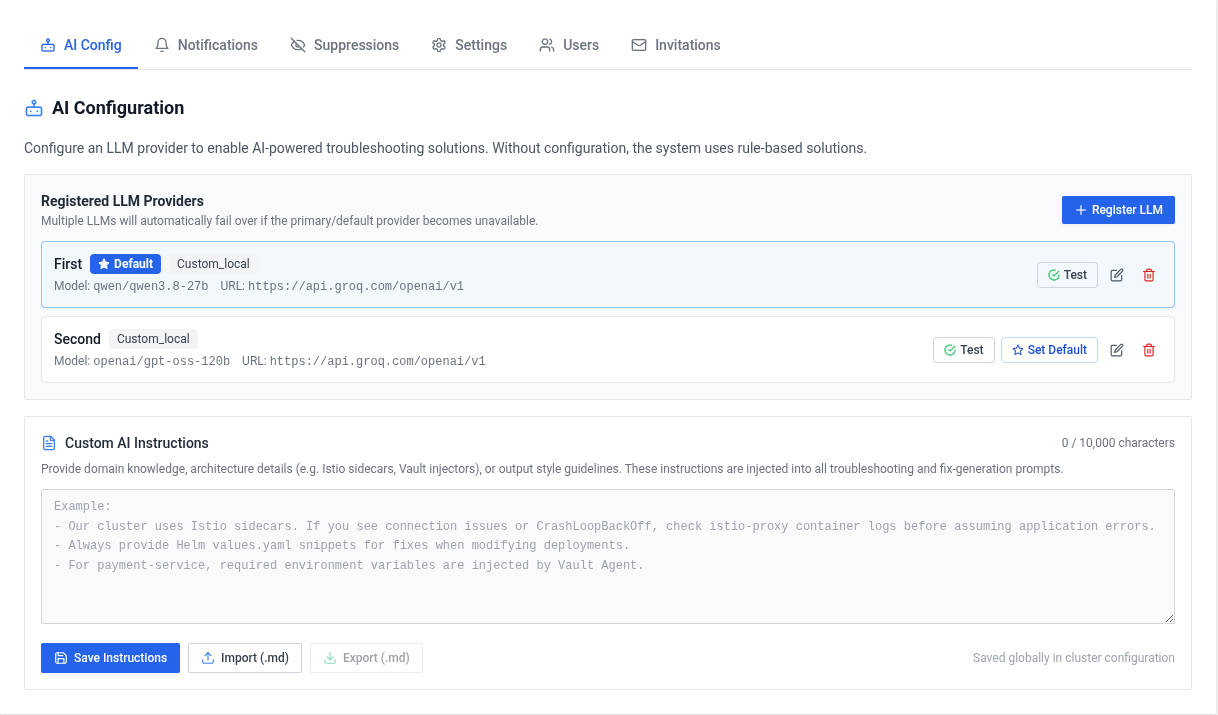
Register multiple AI providers side by side (Ollama, OpenAI, Claude, Gemini, Copilot). Set a primary default with automatic failover, or pick a specific model directly in pod triage.

Teach AI models your cluster topology, service mesh quirks, and team standards. Write, import, and export instructions directly in Markdown without altering code or manifests.

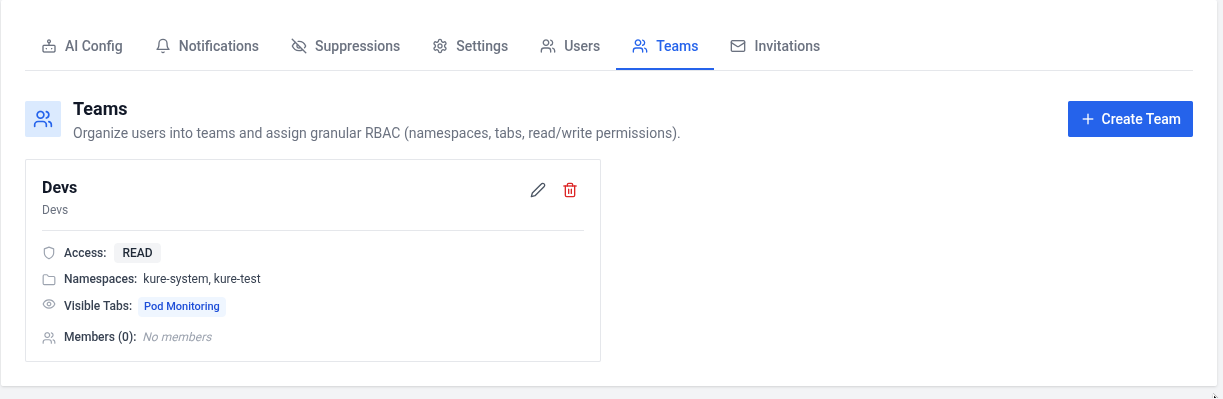
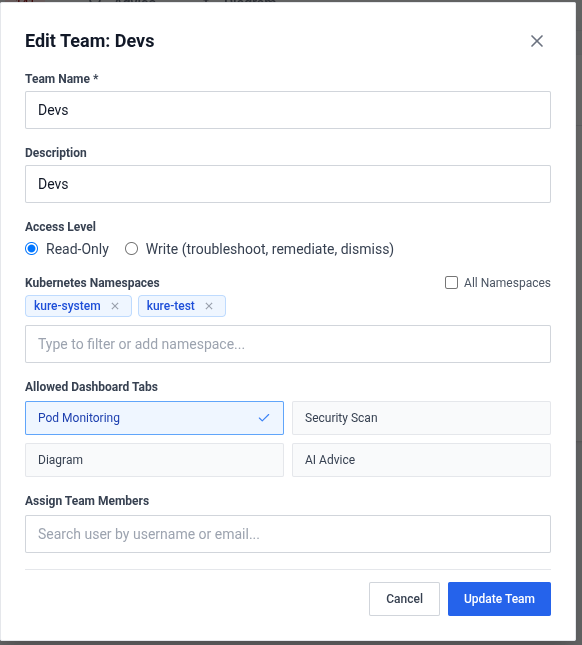
Multi-tenant access control for your cluster. Scope engineer permissions by dashboard tab, namespace boundaries, and read/write mutating privileges.

Enterprise OIDC authentication with group-based access gating, admin role mapping, and secure client secrets via Kubernetes Secrets or runtime UI.
Kure installs cleanly via Helm and stores nothing outside your cluster. Lightweight and resource-friendly.
helm repo add kure-monitor https://kuremonitor.com/
helm install kure-monitor kure-monitor/kure \
--namespace kure-system --create-namespace \
--set postgresql.password="$(openssl rand -hex 24)"Kure focuses on failure diagnosis and security. It complements Prometheus and Grafana — it doesn't replace them.
| Kure does | Kure does not |
|---|---|
| Real-time pod failure detection with AI fixes | Time-series metrics or alerting rules |
| 50+ security misconfiguration checks | Log aggregation or indexing |
| Live topology graph + mirror pod testing | Multi-cluster monitoring |
| Slack / Teams notifications on failure | Replace Prometheus or Datadog |